

What Is Network Latency? What Are the Signs?
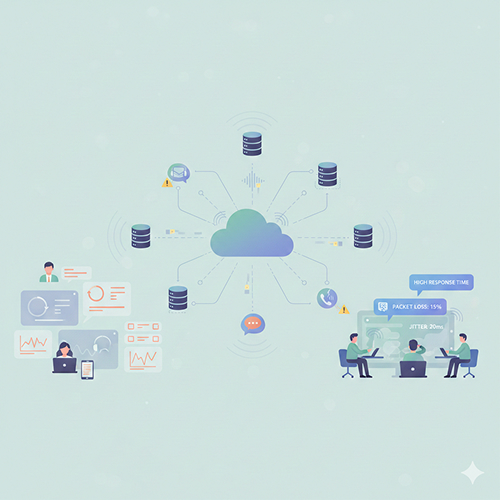
When latency increases within the network or the application layer, an immediate chain reaction begins across the IT environment. Users start reporting slowness to the service desk; web applications respond late, APIs fall into timeouts, and dashboards begin to load empty or incomplete. Meanwhile, operations teams struggle to determine whether the issue originates from the network, the application layer, the database, or the cloud provider, causing internal communication traffic to spike. Monitoring tools simultaneously generate “high response time,” “packet loss,” and “jitter spike” alerts, increasing overall noise levels. VPN tunnels weaken, file transfers fail, and VoIP conversations suffer from audio delays that disrupt critical operations. As each team investigates its own components, the complexity of root-cause analysis grows, demonstrating how even a minor increase in latency can impact the entire service chain. This scenario is a typical example of how high latency can rapidly create systemic stress in modern distributed IT environments.
What Is Latency?
Latency is the delay between an action and the corresponding response. In other words, it is the total time between sending a command and receiving the processed result. It is typically measured in milliseconds (ms) and is a critical metric for communication systems, application performance, network traffic, and overall user experience.
Why Is Latency Important?
When network or application latency rises, the IT environment quickly enters a chain reaction. Users overload the service desk with complaints of slowness and access problems; web applications open slowly, API calls time out, and critical dashboards load empty or with partial data. Meanwhile, operations teams try to identify whether the delay stems from network devices, application code, database queries, or cloud infrastructure, significantly increasing internal coordination load. Monitoring tools generate simultaneous warnings such as “high response time,” “packet loss,” and “jitter.” VPN tunnels become unstable, VoIP and video conferencing sessions suffer from synchronization issues, and file shares drop intermittently. Collectively, these symptoms clearly show how elevated latency creates systemic stress in distributed environments and how even a small delay can impact the entire service delivery chain.
Key Types of Latency
• Network Latency: The delay caused while data packets travel through routers, switches, firewalls, and the internet.
• Application Latency: The processing time required for an application to accept a request, query the database, and return a result.
• Storage Latency: The delay between read/write operations on disk or storage systems.
• Cloud Latency: The delay arising from physical distance, internet quality, or shared resource architecture when accessing cloud environments.
Which Problems Indicate Network Latency?
Network latency becomes visible both through user experience and technical metrics. Below are the most common and reliable indicators:
Slow application and service response
Degradation in VoIP and video conferencing
• Delayed audio
• Echo or overlapping speech
• Frozen video frames
• Pixelation due to packet loss
These symptoms directly indicate latency in interactive services.
Noticeable drop in network throughput
If download/upload speeds appear unusually low while bandwidth is not fully utilized, high latency is often the cause. Low throughput with minimal packet loss is a classic sign of increased latency.
Sudden spikes or fluctuations in ping times (jitter)
• Ping values significantly above normal
• Stable networks showing results fluctuating between, for example, 5 ms and 150 ms
This indicates latency combined with jitter, often related to routing issues, congestion, or wireless interference.
Lag in online games
Delayed character actions or desynchronization with the server are typical indicators of network latency.
VPN instability or slow VPN sessions
VPN tunnels are very sensitive to latency.
• Difficulty establishing tunnels
• Frequent reconnects
• Noticeably slower responses when VPN is enabled
These generally point to high latency, especially when connecting across long distances (e.g., Turkey–Europe).
Delays and timeouts in cloud applications
Slow-loading dashboards, delayed form rendering, and long API response times indicate latency or routing problems.
Delayed IoT/sensor data
Real-time sensor data arriving late or accumulating in batches signals increased latency between the device and the edge/gateway.
Monitoring tools reporting red-flag metrics
Platforms such as SolarWinds, PRTG, Zabbix, and Observability suites commonly raise alerts like:
• High Response Time
• Increased RTT (Round-Trip Time)
• Slow Application Response
• Path Latency Spike
• WAN Link Latency Threshold Breach
These alerts technically validate the presence of latency.
Slow file share access
In SMB/NFS environments, delayed folder loading or prolonged “Preparing to copy…” screens indicate network latency.
If systems respond slower than usual, interactive services lose synchronization, and your monitoring tool reports increased RTT/response time, high network latency is almost certainly present.